Quick answer
Prepare a managed Kubernetes upgrade by checking target-version compatibility, removing API dependencies that will stop working, validating add-ons, and rehearsing node replacement with realistic workload constraints. Use disruption budgets alongside available replacement capacity—not instead of it. Upgrade in controlled stages and verify application behavior after each stage. For Amazon EKS, control-plane rollback is documented within a conditional seven-day window, but it is not a complete application or data rollback. (docs.aws.amazon.com)
This guide uses Amazon EKS with managed node groups as its provider example. The rehearsal assumes a replicated, stateless application in a disposable staging environment. Stateful workloads need additional storage, quorum and recovery checks.
1. Record the upgrade path and component versions
Start with an upgrade record that names the current control-plane version, target version, node versions, maintenance owner and recovery decision-maker.
Use read-only checks to establish the Kubernetes baseline:
kubectl config current-context
kubectl version
kubectl get nodes -o wide
Confirm that the context is the intended cluster before proceeding.
Upstream Kubernetes allows kubectl within one minor version of the API server. A kubelet must not be newer than the API server; newer kubelet releases may be up to three minor versions older. Deployment tools and providers can impose tighter requirements. These are compatibility boundaries, not a recommendation to keep nodes behind indefinitely. (kubernetes.io)
For EKS, plan one control-plane minor-version upgrade at a time. AWS recommends aligning node kubelets with the current control-plane version before starting. If several minor upgrades are necessary, give each transition its own compatibility checks and validation gate. (docs.aws.amazon.com)
Record node operating systems, machine images and custom bootstrap settings too. A Kubernetes version number alone does not describe the node configuration being replaced.
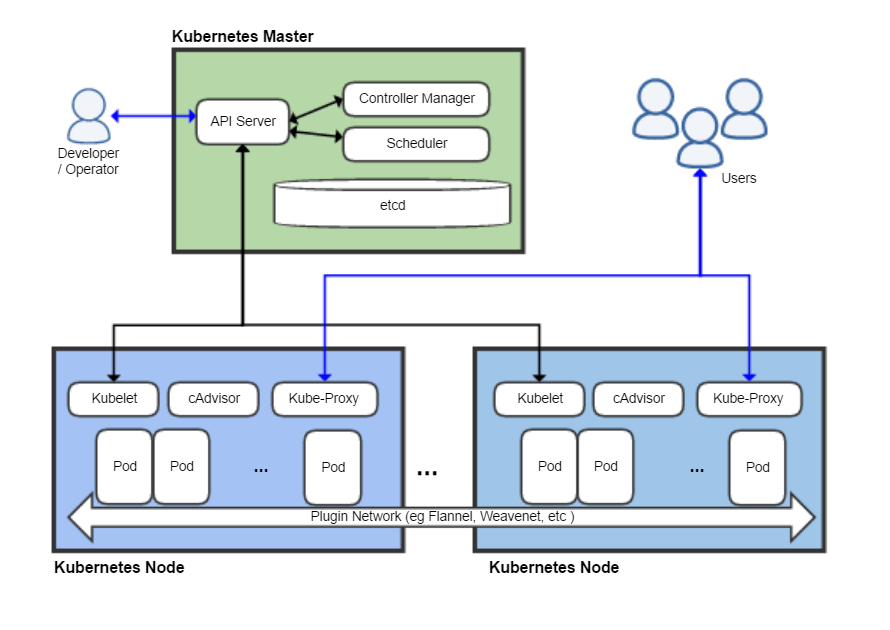

2. Find removed APIs in both configuration and running clients
Review the Kubernetes Deprecated API Migration Guide for every version boundary you will cross. Distinguish an API that is deprecated but still served from one that the target release removes. Migration can require changes to fields or behavior, not just an apiVersion replacement. (kubernetes.io)
Check two different sources of evidence:
- Deployment configuration: rendered Helm charts, generated manifests, GitOps repositories and disaster-recovery definitions.
- Runtime callers: operators, controllers, scripts and integrations that communicate with the Kubernetes API.
AWS recommends checking static rendered manifests as well as live clusters. EKS upgrade insights provide another input, but configuration checks remain important for resources that are not currently deployed. (docs.aws.amazon.com)
A useful historical example is PodDisruptionBudget migration: policy/v1beta1 stopped being served in Kubernetes 1.25. In policy/v1, an explicitly empty selector, {}, selects every Pod in the namespace; previously it selected none. This illustrates why mechanically changing an API version can alter meaning. (kubernetes.io)
For each finding, record the caller or manifest, replacement, owner and validation evidence. Close the issue only after updating the source configuration and exercising the affected operation.
3. Build an add-on compatibility and dependency table
Inventory networking, DNS, storage drivers, ingress controllers, autoscalers, admission webhooks, observability agents and delivery controllers. AWS specifically calls out components that use the Kubernetes API directly when assessing upgrade compatibility. EKS-managed add-ons do not automatically update when the control plane changes. (docs.aws.amazon.com)
Use a table like this:
| Component | Installed version | Target-compatible version | Required timing | Validation |
|---|---|---|---|---|
| Networking | Record actual value | Confirm in component documentation | Before or after control plane, as documented | New Pods obtain connectivity |
| DNS | Record actual value | Confirm compatibility | Record dependency | Service names resolve |
| Storage driver | Record actual value | Confirm compatibility | Record dependency | Volume operation succeeds |
| Admission webhook | Record actual value | Confirm compatibility | Record dependency | Test deployment is admitted |
Do not fill the target column with “latest.” Select a documented compatible release and preserve required configuration.
Identify components that must change before the control-plane upgrade and those that can change afterward. AWS notes that some controllers require a pre-upgrade update or configuration change. Treat that requirement as a dependency, not an exception discovered during maintenance. (docs.aws.amazon.com)
4. Check disruption budgets and usable replacement capacity
A PodDisruptionBudget, or PDB, limits qualifying voluntary disruptions through the eviction API. It does not prevent involuntary failures. Deployment and StatefulSet rolling updates are also not constrained by PDBs; their rollout behavior is controlled separately. Avoid combining application releases with node maintenance unless that interaction has been deliberately rehearsed. (kubernetes.io)
Inspect the budgets before maintenance:
kubectl get pdb -A
For a selected application, examine currentHealthy, desiredHealthy and disruptionsAllowed. Kubernetes counts a Pod as healthy for this purpose when its Ready condition is true. A budget allowing no disruptions deserves investigation before a drain begins. (kubernetes.io)
Capacity planning must also account for the provider’s replacement mechanism. EKS’s default managed-node update strategy creates replacement nodes before terminating old ones. Its scale-up phase can launch more nodes than the configured number being upgraded concurrently. Instance quotas, Availability Zone capacity and node bootstrap failures can block replacement. (docs.aws.amazon.com)
Make these practical checks part of the rehearsal:
- Can replacement nodes launch and become Ready?
- Can displaced Pods run outside the node being removed?
- Are placement constraints compatible with the remaining nodes?
- Do replacement nodes have the required labels, taints and configuration?
- Is temporary additional capacity approved?
Do not assume “one node unavailable” means “one extra node needed.” Size headroom against the documented update behavior and the workload’s observed rescheduling requirements.

5. Rehearse a three-replica application in staging
The following is an illustrative, untested rehearsal, not a production-ready application definition.
Assume an existing staging Deployment named upgrade-demo in namespace upgrade-lab. It has three Ready replicas, matching Pod labels app: upgrade-demo, readiness probes and tested graceful shutdown. For this exercise, confirm that its replicas occupy separate nodes and that replacement capacity is available.
An illustrative PDB is:
apiVersion: policy/v1
kind: PodDisruptionBudget
metadata:
  name: upgrade-demo
  namespace: upgrade-lab
spec:
  minAvailable: 2
  selector:
    matchLabels:
      app: upgrade-demo
With three healthy replicas and a requirement for two, the initial allowance is:
3 healthy − 2 required = 1 permitted disruption.
If one replica is already unhealthy, the allowance becomes 2 − 2 = 0. This is why an apparently conservative budget can block maintenance when the workload is degraded. (kubernetes.io)
Rehearse the following sequence:
- Establish a baseline using representative requests and application health checks.
- Verify the selector, replica placement and PDB status.
- Perform the planned staging control-plane upgrade.
- Select one staging node hosting a replica.
- Drain that node, then observe replacement scheduling and readiness.
- Continue only after application checks pass.
The staging-only drain command is:
kubectl drain <staging-node-name> --ignore-daemonsets
A normal drain respects PDBs and graceful termination. --ignore-daemonsets permits the operation to proceed without evicting DaemonSet-managed Pods. Do not add force or deletion flags merely to make a blocked rehearsal pass. (kubernetes.io)
Watch the workload:
kubectl get pods -n upgrade-lab -l app=upgrade-demo -o wide
kubectl get pdb upgrade-demo -n upgrade-lab -o yaml
kubectl get events -n upgrade-lab --sort-by=.metadata.creationTimestamp
Define pass conditions beforehand: replacement becomes Ready, representative requests meet your acceptance criteria, and no unexplained scheduling or application errors remain.
If the retained node is safe to return to service, uncordon it:
kubectl uncordon <staging-node-name>
Uncordoning restores scheduling eligibility; it does not reverse the control-plane upgrade. (kubernetes.io)
6. Upgrade EKS in stages, with explicit validation gates
After satisfying pre-upgrade dependencies, follow the EKS-documented sequence: prepare the cluster, upgrade the control plane to the next minor version, update nodes, then update additional applications, EKS add-ons and clients as required. Component-specific prerequisites still take precedence over this high-level sequence. (docs.aws.amazon.com)
Use this operational pattern:
- Control-plane gate: verify update completion and essential API operations.
- Initial node-group gate: update a selected lower-risk group and validate workload behavior.
- Remaining node-group gates: proceed group by group after checks pass.
- Component gate: validate networking, DNS, storage and controller changes individually.
These gates are a proposed planning framework, not an EKS guarantee of disruption-free operation.
For managed node groups, understand the selected update strategy. AWS recommends the default strategy in most scenarios because it creates capacity before removing old nodes. The minimal strategy terminates old nodes before creating replacements, avoiding a temporary capacity increase but changing the availability trade-off. (docs.aws.amazon.com)
A PDB-related PodEvictionFailure is a reason to investigate workload health and eviction constraints. EKS documents force deletion as an option, but it should not be the routine response to a failed drain. (docs.aws.amazon.com)
7. Define recovery without assuming a universal downgrade
Separate three recovery actions in the runbook: reverting application configuration, replacing problematic nodes, and reverting the control-plane version.
As checked on October 4, 2026, EKS documents control-plane rollback to the previous minor version within seven days of an in-place upgrade completing. Eligibility conditions include supported versions, cluster status and feature compatibility. This is neither an unrestricted downgrade nor a promise that every cluster can roll back. (docs.aws.amazon.com)
EKS rollback preserves cluster state and customer data; it is not a point-in-time restore. Add-ons are not automatically reverted. For this guide’s managed-node-group environment, nodes require separate handling, and compatible worker versions must be established before reverting the control plane. Auto Mode has different documented node-rollback behavior. (docs.aws.amazon.com)
Also distinguish provider infrastructure protection from workload recovery. Once an EKS control-plane upgrade starts, it cannot be paused or stopped. AWS may revert the infrastructure deployment if its own readiness checks fail, but that does not replace application validation after a successful upgrade. (docs.aws.amazon.com)
Before production, document a forward-fix path and, where necessary, a tested workload-and-data recovery path to another supported cluster. Do not make “downgrade if needed” the entire recovery plan.
8. Use a go/no-go checklist and verify user-facing behavior
Use the following checklist as a proposed approval record. Attach evidence rather than checking boxes from memory.
Go only when:
- The current-to-target version path is documented.
- Removed-API findings have owners and validated fixes.
- Add-on versions and upgrade dependencies are confirmed.
- Workload health and PDB allowances support the planned maintenance.
- Replacement nodes and displaced Pods succeeded in staging.
- Application acceptance criteria and stop conditions are agreed.
- Recovery actions, permissions and responsible owners are recorded.
These checks combine the provider’s compatibility guidance with Kubernetes eviction behavior. A successful control-plane update alone is not the completion criterion. (docs.aws.amazon.com)
After each stage, compare the following against the baseline:
| Check | Evidence to capture |
|---|---|
| Nodes | Expected versions, Ready status and configuration |
| Workloads | Replica readiness, restarts and scheduling events |
| Application | Representative transactions and agreed latency/error criteria |
| Platform services | DNS, networking, ingress, storage and controller operations |
| Recovery readiness | Current rollback eligibility and dependency compatibility |
If replacement Pods stay Pending, investigate before removing more capacity. If drain is blocked, inspect workload health and the budget. If nodes are Ready but transactions fail, treat the application check as the failed gate.
Keep temporary capacity until validation is complete. Then remove rehearsal resources and approved temporary capacity through the normal change process. Record what failed, what changed and what evidence should be required for the next upgrade.